About
Hello! My name is Aditya Tanna, and I am a Research Scientist at Lexsi Labs, where I lead the tabular foundation model team. I study what these models learn from synthetic pretraining, how adaptation changes that knowledge, and how much remains after compression.
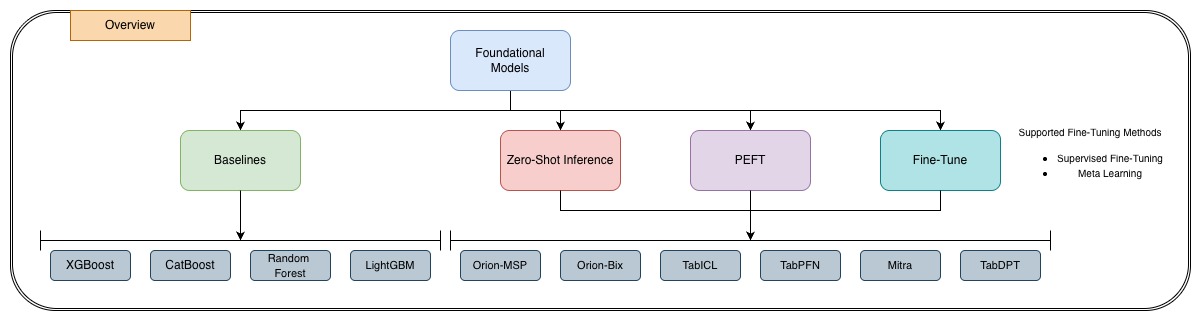
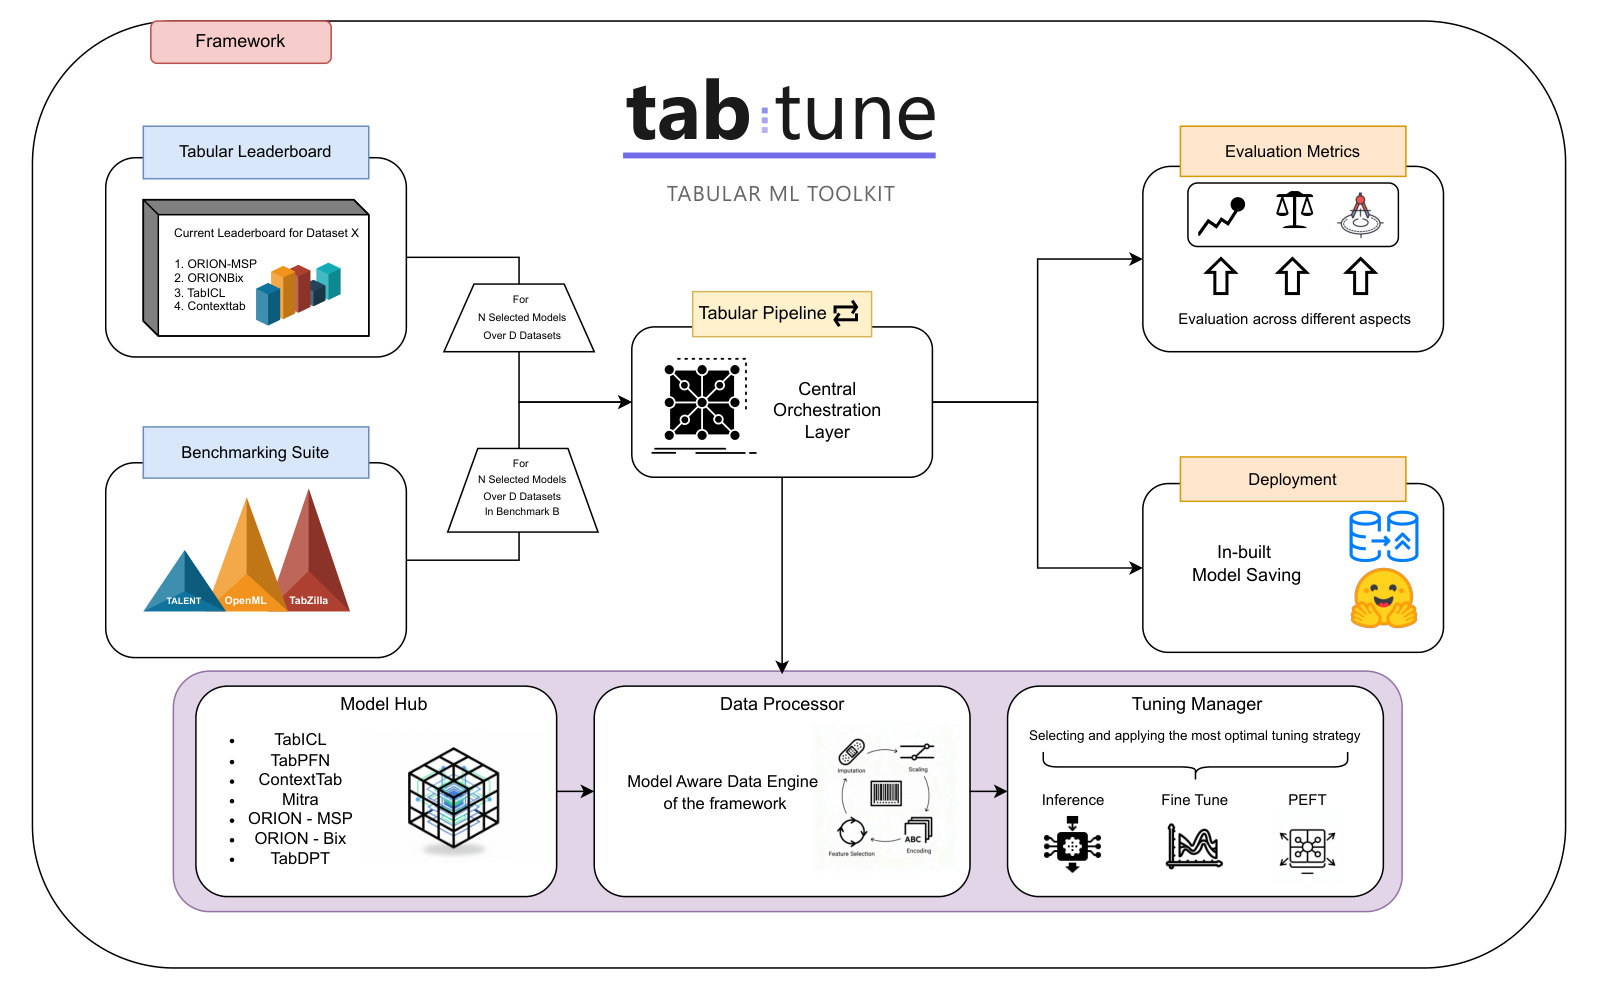
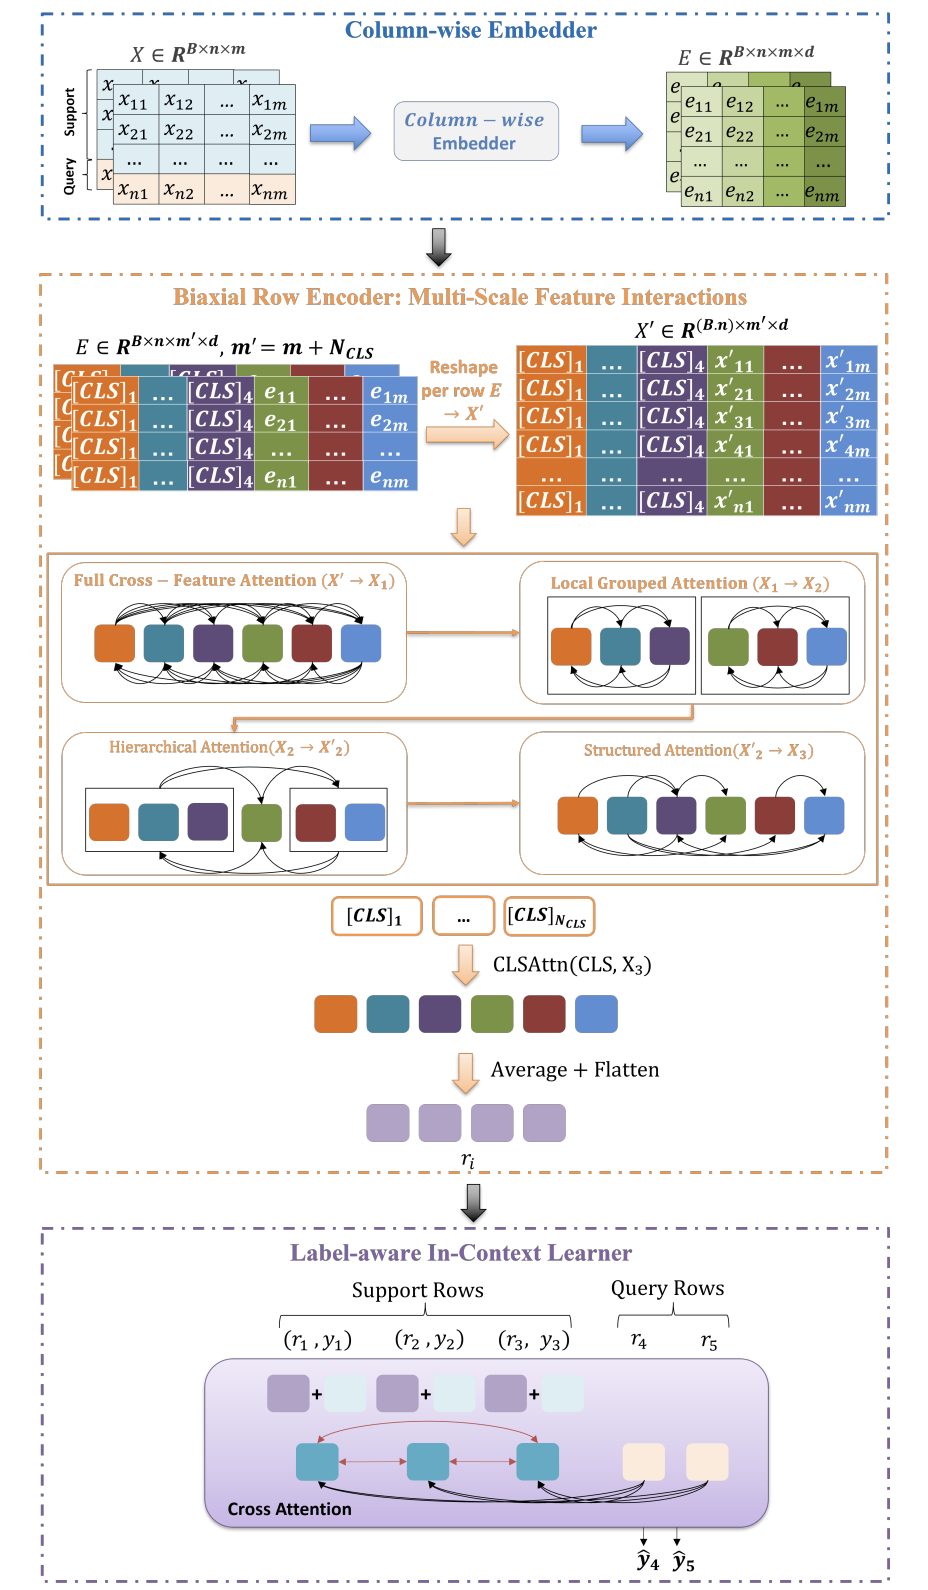
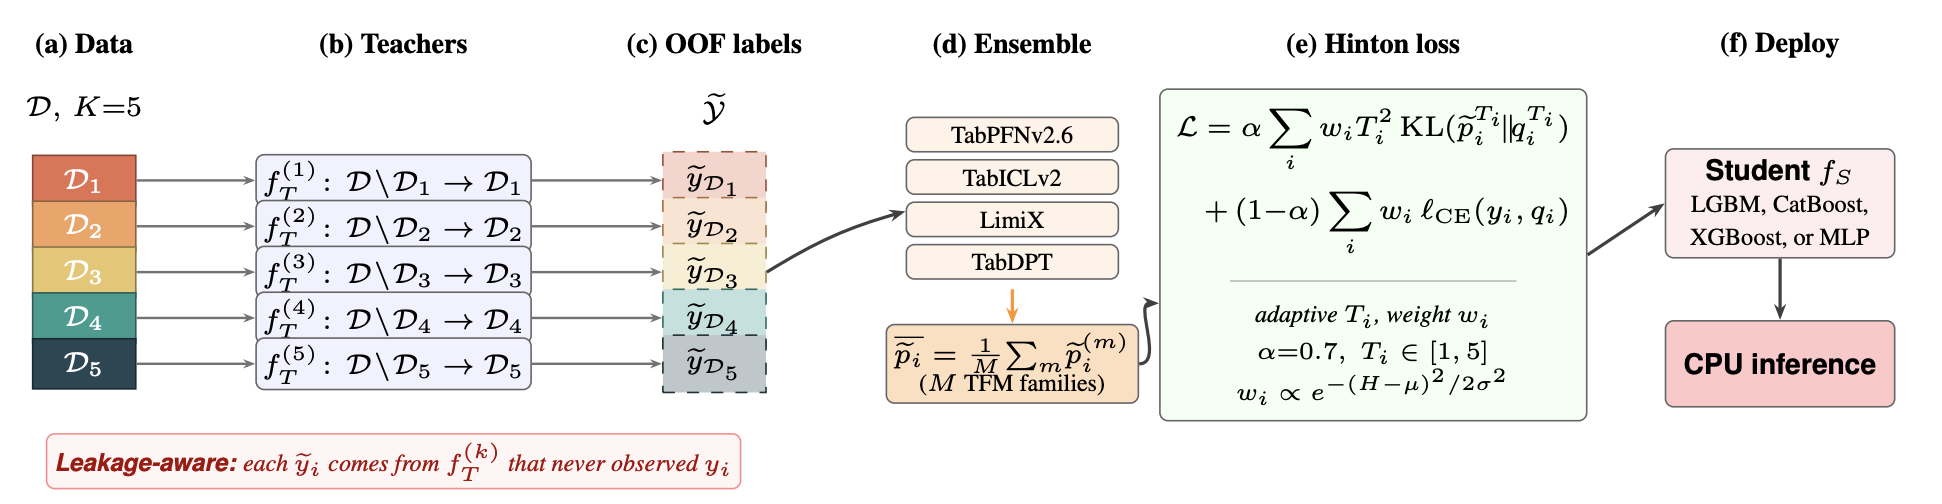
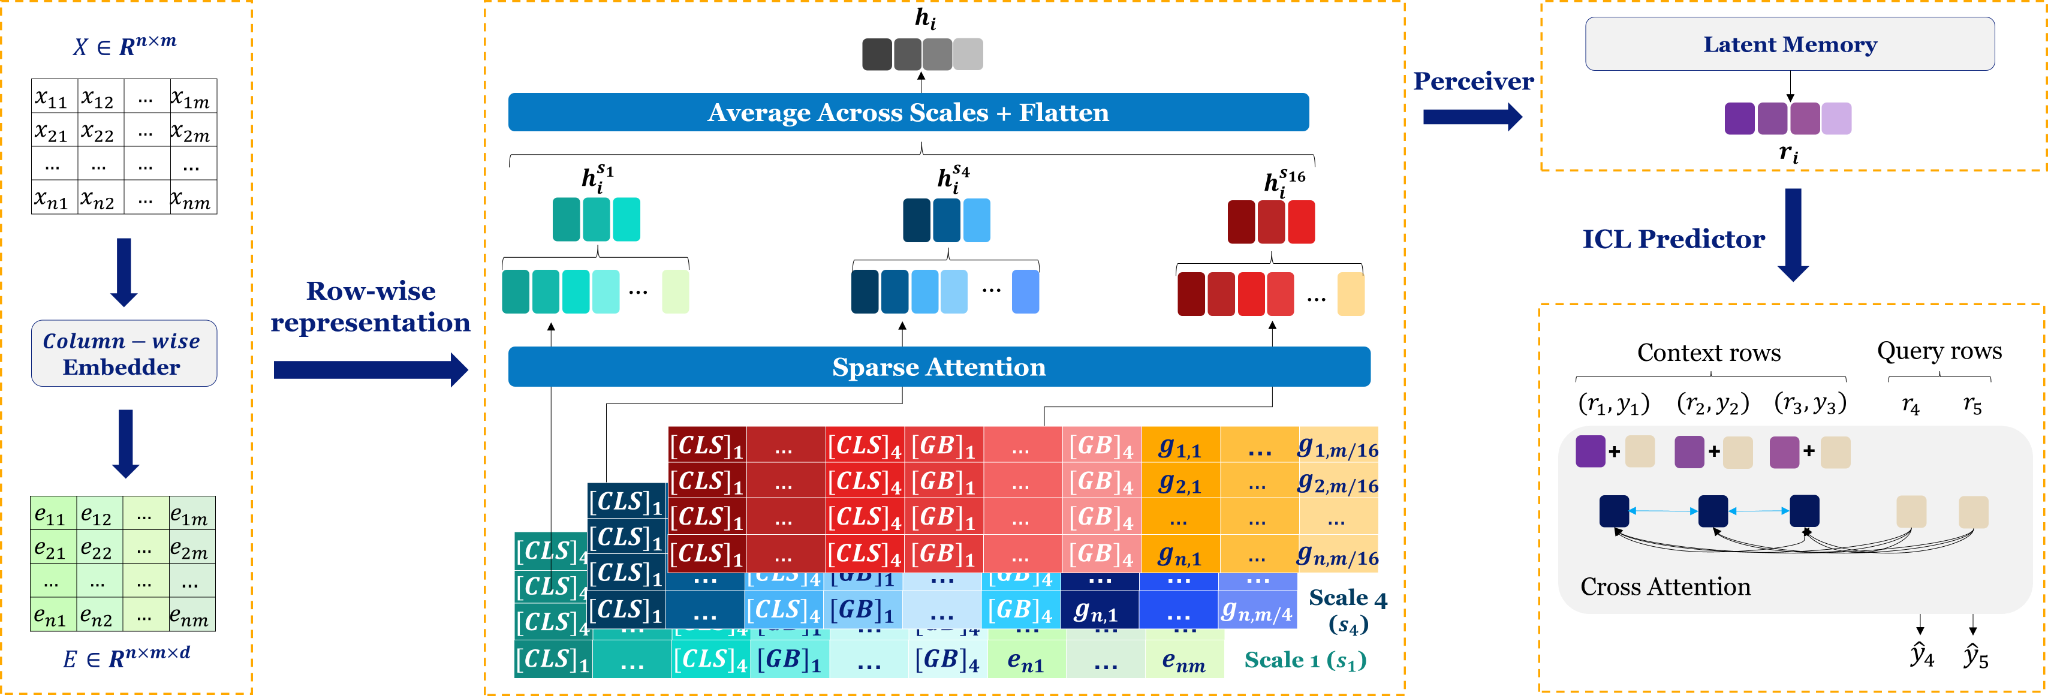
I built and maintain TabTune, our open-source library that brings more than ten tabular foundation models under one interface for inference, meta-learning, and fine-tuning [WWW ’26]. My research explores fine-tuning and calibration [WWW ’26], distillation into CPU-ready students [SD4H ’26], the limits of ensembling [FMSD ’26], and attention architectures designed for tables [WWW ’26, EurIPS ’25]. I was selected for the Google DeepMind APAC Research Symposium in Bengaluru in October 2026 to present my research around Clinical RL.
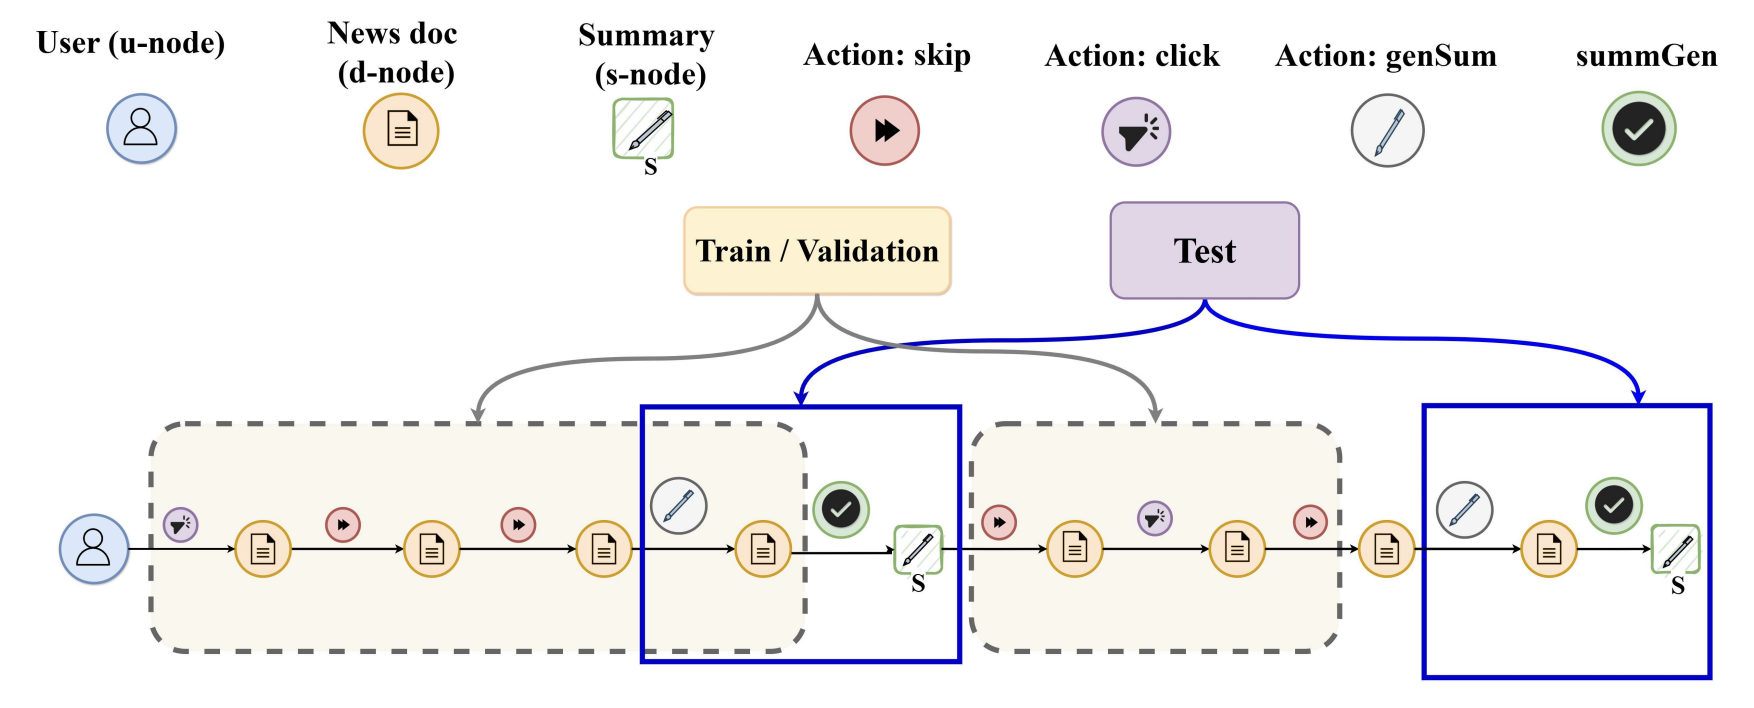
Previously, I was a Research Assistant with Prof. Sourish Dasgupta at the Knowledge and Discovery Lab, working on preference-diversity augmentation for personalized summarization [TMLR ’25]. My undergraduate thesis with Prof. Abhishek Jindal investigated ontology-grounded reinforcement learning for clinical question answering [CIKM ’26]. I completed my B.Tech. in Mathematics and Computing at Dhirubhai Ambani University (formerly DA-IICT), with a merit scholarship in all eight semesters.
Keywords: Tabular Foundation Models, Pretraining Priors, Fine-Tuning, Calibration, Distillation, In-Context Learning
If you’d like to discuss my research or a collaboration, feel free to reach out via email!
Last updated: October 2026
Timeline
• September 2026: Two papers accepted to the ATTRIB Workshop at NeurIPS 2026!
• May 2026: Our work on distilling tabular foundation models for structured health data received a Spotlight at SD4H @ ICML. Our credit-risk study received an Oral presentation at FinDS @ SIGMOD/PODS.
• January 2026: TabTune, our fine-tuning study, and Orion-BiX appear at The Web Conference (WWW). Our ontology-grounded clinical QA work appears at CIKM.
• October 2025: Our personalized summarization work, PerAugy, was published in TMLR. Orion-MSP was presented at AITD @ EurIPS.
• August 2025: Joined Lexsi Labs as a Research Scientist, leading research on tabular foundation models.
• May 2025: Completed my B.Tech. in Mathematics and Computing at Dhirubhai Ambani University.
• January 2024: Began working with Prof. Sourish Dasgupta as a Research Assistant at the Knowledge and Discovery Lab.
Publications
C = Conference or journal · W = Workshop or preprint
Conference and journal
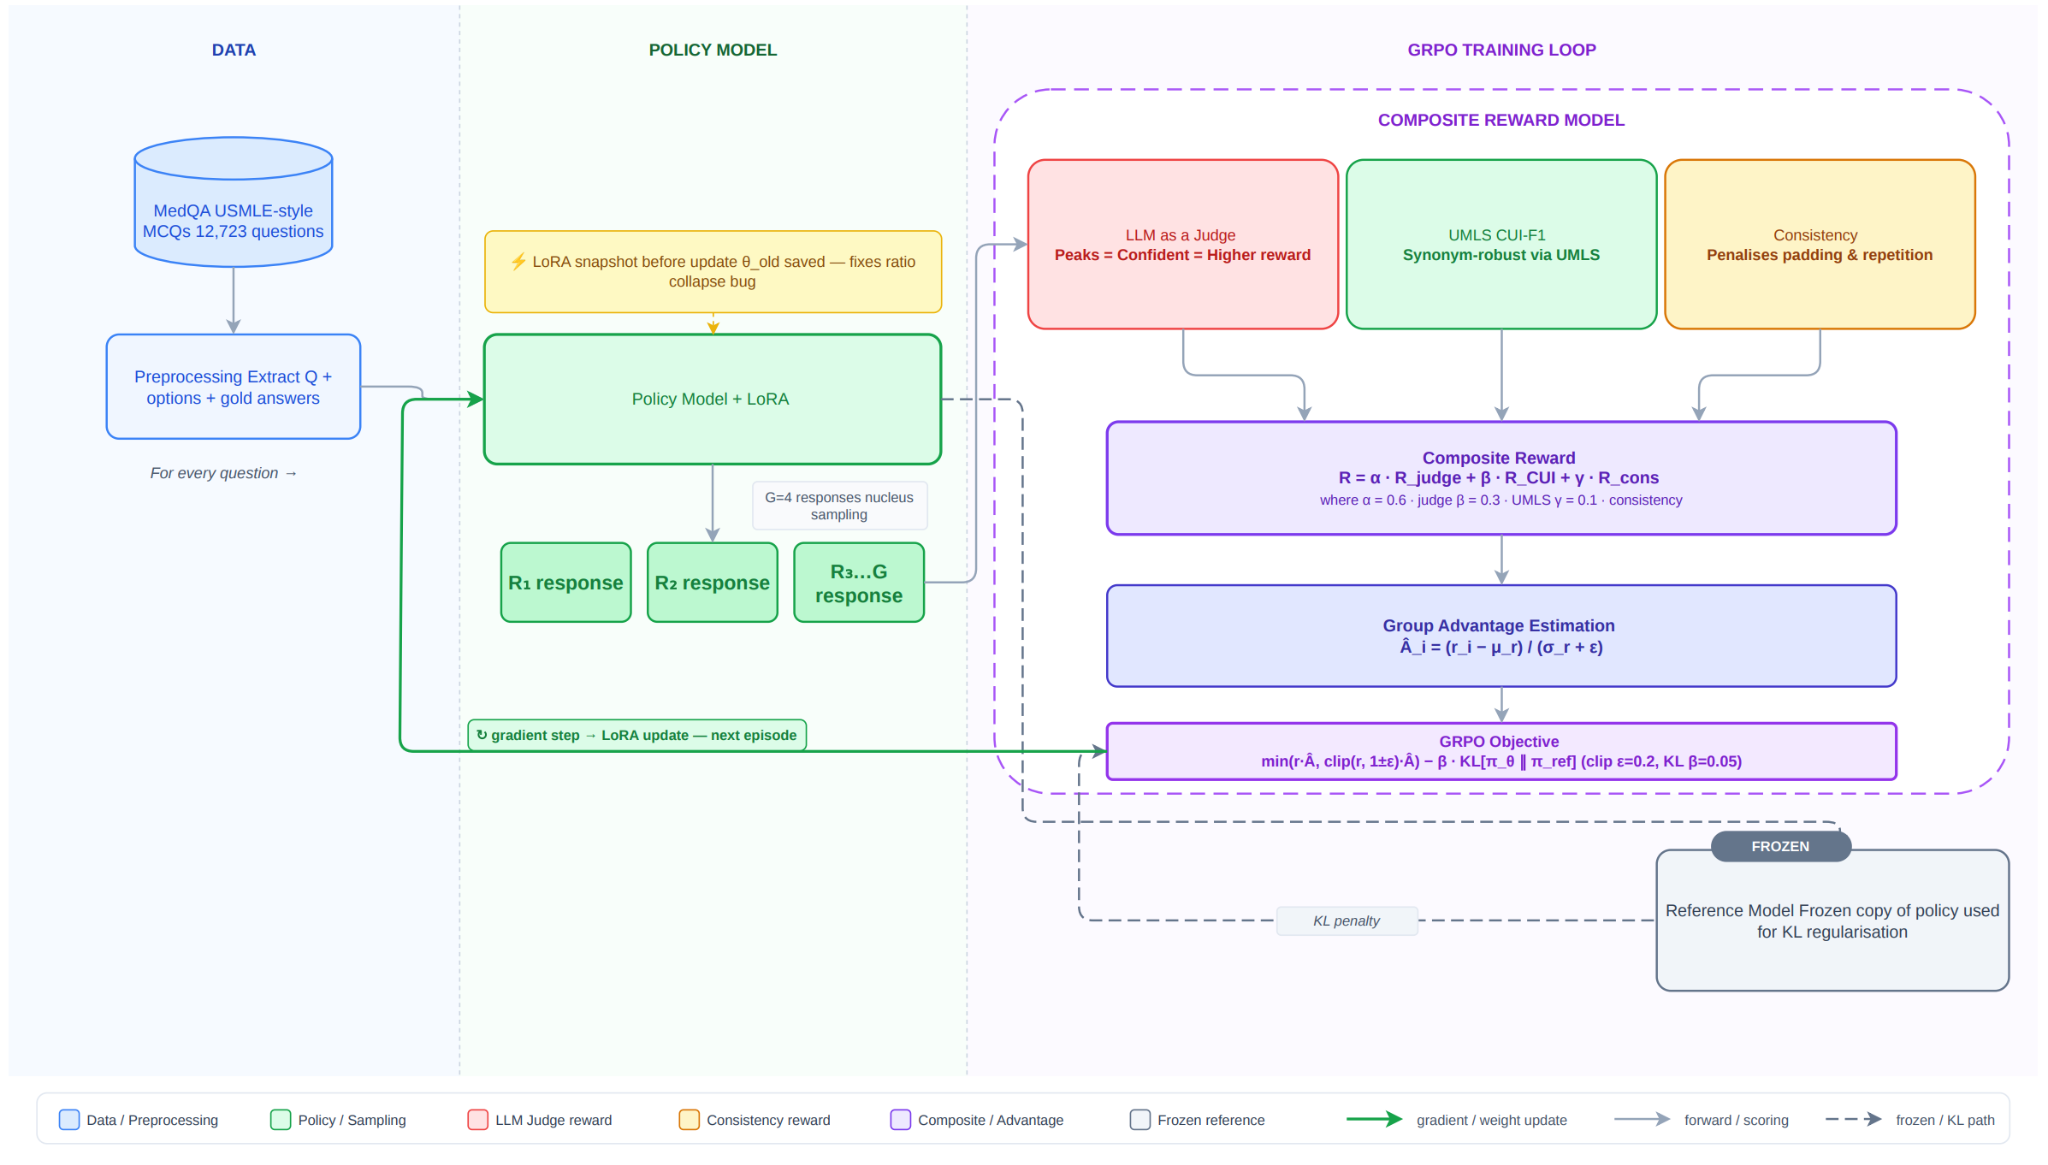
[C.3] Ontology Concept Overlap as a Training Signal: Knowledge-Grounded Reinforcement Learning for Clinical Question Answering
, Abhishek Jindal
CIKM 2026
Workshop and preprint
[W.1] From Behavior to Provenance: Attributing Tabular Foundation Models to Synthetic Pretraining Data
Mohamed Bouadi, Nassim Bouarour, Shivam Dubey, , Vinay Kumar Sankarapu
ATTRIB Workshop @ NeurIPS 2026
[W.2] When Does Synthetic Relational Data Teach Models to Use Relations? Tracing Predictive Structure from Pretraining Data to Model Behavior
Shivam Dubey, Mohamed Bouadi, Nassim Bouarour, Varun Kulkarni, , Vinay Kumar Sankarapu
ATTRIB Workshop @ NeurIPS 2026
[W.4] Data Presentation Over Architecture: Resampling Strategies for Credit Risk Prediction with Tabular Foundation Models
, Mitul Solanki, Mohamed Bouadi, Nassim Bouarour, Pratinav Seth, Vinay Kumar Sankarapu
Oral · FinDS Workshop @ SIGMOD/PODS 2026
[W.6] Ensembling Tabular Foundation Models: A Diversity Ceiling and a Calibration Trap
, Yash Desai, Pratinav Seth, Mohamed Bouadi, Nassim Bouarour, Vinay Kumar Sankarapu
FMSD Workshop @ ICML 2026
[W.7] Shaping the Prior: How Synthetic Task Distributions Determine Tabular Foundation Model Quality
Mohamed Bouadi, Nassim Bouarour, Vaibhav Kulkarni, Shubham Dubey, , Vinay Kumar Sankarapu
FMSD Workshop @ ICML 2026
Projects
TabTune: A Unified Tabular ML Toolkit
An open-source library for inference, meta-learning, supervised fine-tuning, and parameter-efficient adaptation across 10+ tabular foundation models. Includes calibration and fairness evaluation, with extensions for conformal prediction, row-feature attribution, and prediction provenance.
Forty8: Calibrated World Cup Forecasting
A probabilistic forecasting engine for the 2026 World Cup. Combines rating, goal, market, and squad-strength models using a log-opinion pool, then simulates 300,000 tournament outcomes. Uses walk-forward backtesting, Brier scores, and completed-match constraints to produce calibrated, results-conditioned forecasts.
Teaching & Service
At Dhirubhai Ambani University, I was a Teaching Assistant for Object Oriented Programming with Prof. Sourish Dasgupta (January–June 2025), Database Management Systems with Prof. Amit Mankodi (July–December 2024), and Big Data Processing with Prof. PM Jat (July–December 2024).
Reviewer:ICLR 2027, ML4H 2026, NeurIPS 2026 (Main and Workshop: XAI4Science) , CIKM 2026, ICML 2026 Workshops (SD4H and FMSD).